This is one of the clearer, more disciplined pieces I’ve seen on the AI-coding reality check. Gerty takes the Ars Technica write-up of the Chen & Stratton Harvard working paper and actually does the work: digs into the primary numbers, cross-checks with METR’s RCTs, GitClear’s maintainability data, Veracode’s security results, the SWE-bench variants, and the multi-language efficiency benchmarks. The result is a 22-minute read that stays grounded instead of sliding into either boosterism or “AI is useless” fatalism.
What the piece gets right
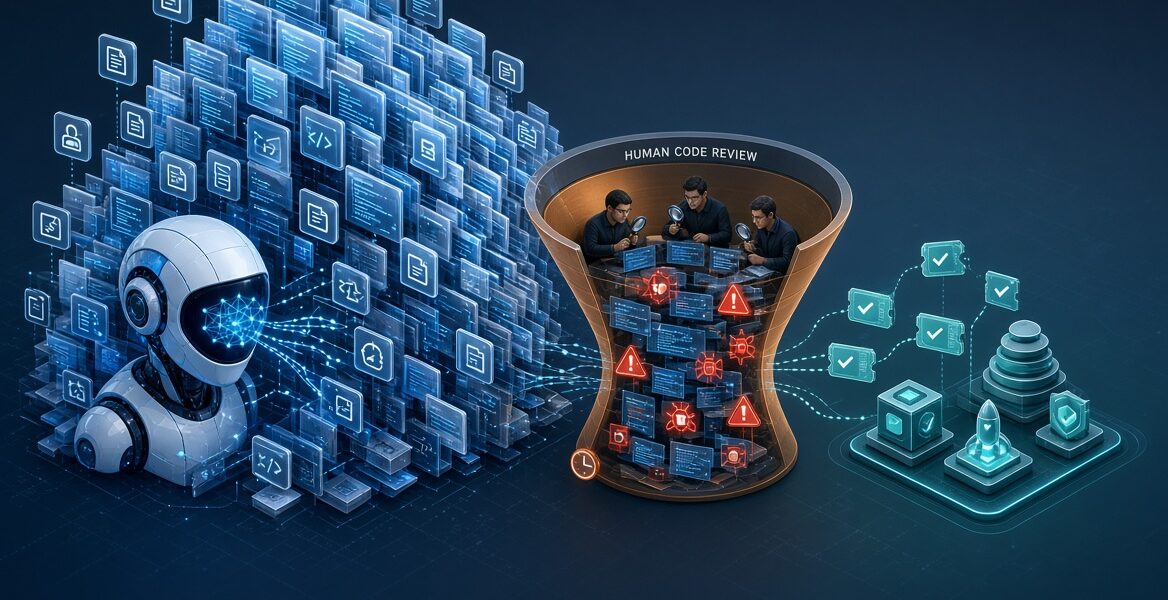
The core finding is stated cleanly and repeatedly: after firms adopt coding agents, lines of code, commits, and PRs jump (30 %, 20 %, 23 %), but resolved Jira issues and epics do not move in a statistically significant way. The extra throughput is absorbed downstream—PR-to-merge time up 49 %, change-request rate nearly doubles, review comments up 35 %, more engineers pulled into reviewing. That is textbook theory-of-constraints applied to software. Intermediate metrics (LOC, commit volume) have become actively misleading; the paper’s authors and this article both flag that managers who optimize for them will misread the ROI.
The METR randomized trials are handled with appropriate caution. Experienced maintainers on large, familiar codebases were 19 % slower with early-2025 tools while still believing they were faster. The later follow-up shows a weak point-estimate speedup whose confidence intervals cross zero and is contaminated by selection (people refusing to work without AI). Perception gap is real and persistent; self-reports remain large while instrumented gains stay modest or negative for high-context expert work. Greenfield, boilerplate, tests, and unfamiliar codebases are the clear wins—exactly where the article places them.
On quality the evidence is consistent and uncomfortable: duplication up 81 %, refactoring (“moved” code) collapsed from ~21 % to 3.8 % of changed lines, function connectivity down 35 %, error-masking up. AI produces more isolated, more verbose, less efficient code (best models ~62 % of human-expert runtime efficiency on EffiBench-X). Security is the weakest link—roughly 44–45 % of generation tasks still introduce known OWASP vulnerabilities when security is not explicitly requested, and the pass rate barely budged from 2025 to 2026. Treating AI output as a draft that must be scanned and reviewed is the only rational policy.
Model rankings and language effects are treated with the right skepticism. Claude currently leads the public leaderboards, open-weight models are within a point, and moving to contamination-resistant or private-codebase evaluations drops scores by 30+ points. Python-heavy benchmarks overstate performance on the rest of the stack. All of that matches what people actually see in production.
The practical recommendations at the end are the strongest part of the piece: measure outcomes (issue resolution, review latency, rework, change-failure rate), invest in the verification stage, mandate security scanning, budget for the maintainability debt that is accumulating, use AI where it demonstrably wins, and evaluate models on your code in your languages. That is the correct managerial response.
Caveats the article already flags (and a couple more)
It is still a working paper based on opt-in Jellyfish client data, firm-level adoption measures dilute individual effects, and the data end in March 2026. Agents and review tooling have continued to improve. GitClear and Veracode both sell tooling that benefits from highlighting quality and security problems; the article notes this and points to corroborating academic work, which is fair. The open questions section is honest: we still lack clean instrumented productivity numbers for the newest agents, we do not yet know how much explicit security/maintainability prompting closes the gaps at firm scale, and the long-term skill-formation and review-pipeline effects remain under-studied.
One mild under-emphasis: the article correctly notes that AI review tooling is still thin (only ~10–23 % of comments/PRs getting AI assistance in the study window). If that layer matures faster than expected, the bottleneck can move again. Whether organizations will actually trust automated security review at scale is a different question.
Overall take
This is evidence synthesis done properly. It does not claim AI coding is a failure; it shows that the generation step has become cheap while the verification, integration, security, and long-term ownership steps have not scaled with it. The industry has already won the “more code” battle. The next, harder battle is more software—reliable, maintainable, secure software that actually ships and stays shippable. Until the review and validation bottlenecks move, the data will keep looking like this: more activity, flat outcomes, rising technical debt.
Useful reality check. Worth circulating to any team still measuring success primarily by lines of code or agent adoption rates.